
Loading, please wait...
Loading, please wait...
Public discourse in India is increasingly threatened by the rapid spread of digital falsehoods. Consequently, understanding the efficacy of AI misinformation detection has become crucial for healthcare providers who encounter patients influenced by social media. A recent evaluation study highlights how large language models (LLMs) like GPT-4 Turbo are performing in this complex landscape compared to human experts.
The study compared four OpenAI models against human annotators using the MuMiN dataset. Specifically, researchers focused on tasks requiring cognitive analysis and complex judgment. Results showed that GPT-4 Turbo, when using chain-of-thought prompting, achieved an accuracy of 67.2%. In contrast, human annotators maintained a superior performance with 70.1% accuracy and an F-score of 81%.
Furthermore, the research identified specific areas where AI struggles. While LLMs excel at logical reasoning and straightforward detection, they often fail to detect sarcasm or user intent. This is particularly relevant in the Indian context, where medical misinformation is frequently wrapped in cultural nuances and local dialects. Human moderators remains essential for identifying these subtle cues.
Researchers tested various prompting strategies to improve the performance of these models. These included zero-shot, few-shot, and chain-of-thought (CoT) methods. Interestingly, CoT prompting significantly boosted the model's ability to interpret complex misinformation. However, the study also found that LLM confidence scores do not always correlate with accuracy in difficult tasks. This discrepancy suggests that AI can be confidently wrong when dealing with nuanced health claims.
Clinicians in India should remain cautious when relying on automated tools. According to a 2024 World Economic Forum report, India faces the world's highest risk of misinformation-driven social instability. For instance, false claims about vaccines and lifestyle diseases continue to circulate on platforms like WhatsApp. Therefore, while AI tools offer scalability for moderation, human expertise remains indispensable for final clinical verification in practice.
No, the study indicates that LLMs struggle with complex judgments like detecting sarcasm and understanding nuanced user intent in social media posts.
Chain-of-thought (CoT) prompting yielded the highest performance for detecting misinformation among all tested OpenAI models, though it still trailed human accuracy.
Disclaimer: This content is for informational and educational purposes only. It does not constitute professional medical advice, diagnosis, or treatment. Always seek the advice of your physician or other qualified healthcare provider with any questions you may have regarding a medical condition. Refer to the latest local and national guidelines for clinical practice.
References
Wojtczak DN et al. Performance of Large Language Models in the Cognitive Analysis of Misinformation: Evaluation Study. JMIR Infodemiology. 2026 May 18. doi: 10.2196/72524. PMID: 42149639.
Klang E, Nadkarni G, et al. Medical misinformation more likely to fool AI if source appears legitimate. The Lancet Digital Health. 2026 Feb 11.
World Economic Forum. Global Risks Report 2024: India Misinformation and Disinformation Analysis.
"
Read summarized clinical updates, watch expert medical content, and earn CME certifications right from your smartphone.
Open your smartphone camera to scan and install.
Study compares AI models like GPT-4 to humans in detecting misinformation, finding that humans still lead in complex, nuanced medical analysis....
5 months ago
Review how tailored exercise programs benefit frail older patients with heart failure. Explore pathophysiological mechanisms, individualized training prescriptions, and strategies to overcome adherence barriers in clinical practice.
Today
Leucine Rich Bio has introduced South Asia's first comprehensive vaginal microbiome test, BugSpeaks. By profiling microbial dysbiosis, pathogens, and antimicrobial resistance, this next-generation diagnostic platform provides clinicians with deeper insights into recurrent infections, fertility, and reproductive health.
Today
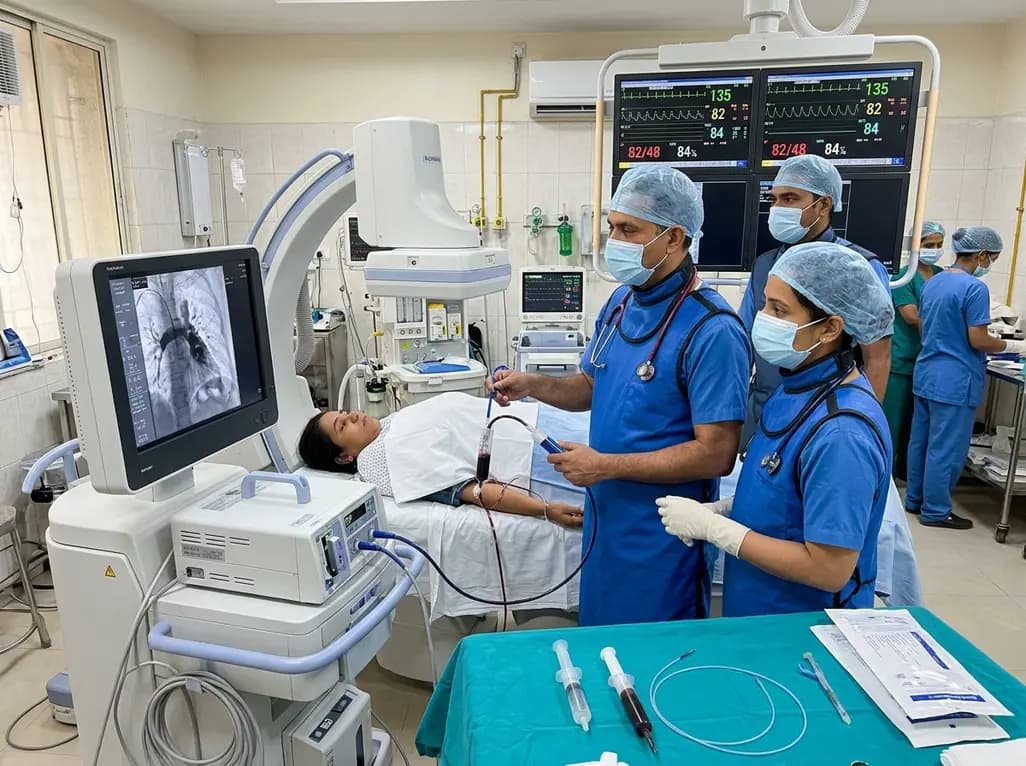
In high-risk pulmonary embolism complicated by severe anemia and active uterine bleeding, systemic thrombolysis is contraindicated. Large-bore aspiration thrombectomy provides rapid hemodynamic rescue without fibrinolysis, supported by inferior vena cava filter placement and multidisciplinary critical care.
Today
This comparative study evaluates posterior labral tears with and without glenohumeral instability, highlighting distinct demographic patterns, MRI underestimation in stable shoulders, and successful arthroscopic repair outcomes.
Today
A clinical study demonstrates that early intervention with tocilizumab, either as monotherapy or bridged with corticosteroids, achieves significant proptosis reduction and resolves active inflammation in treatment-naive thyroid eye disease.
Today