Loading, please wait...
Loading, please wait...
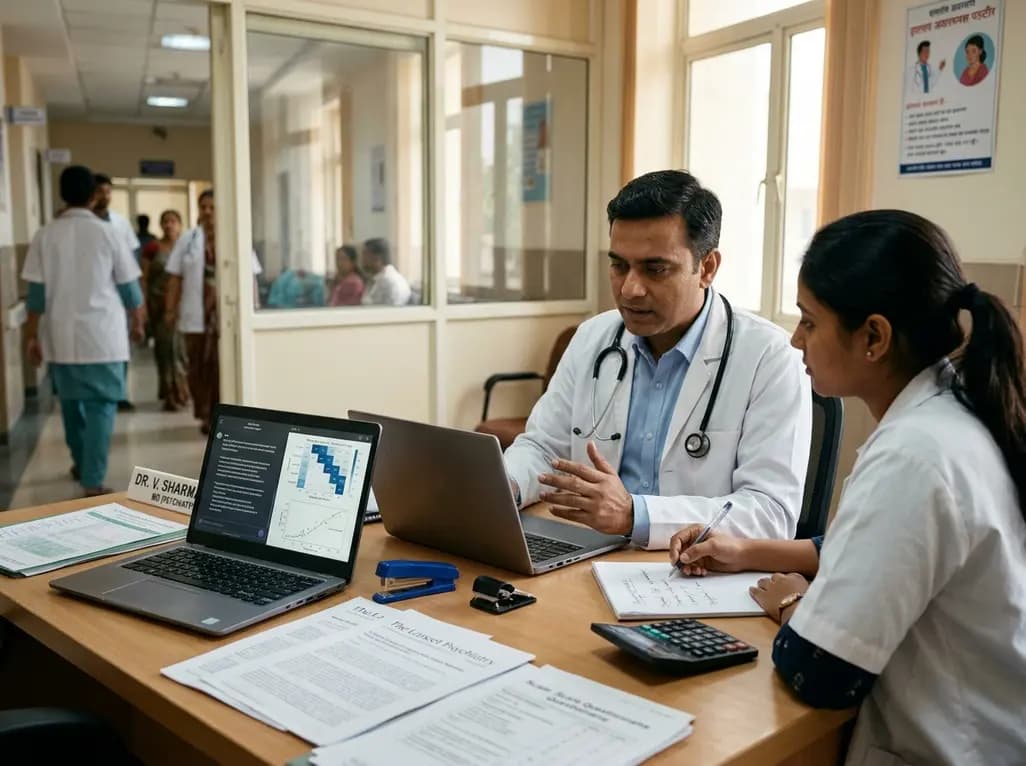
Artificial intelligence continues to transform behavioral science, sparking extensive exploration into the utility of LLMs in psychological research. Mental health clinicians and clinical researchers routinely rely on validated psychometric instruments to assess complex psychiatric conditions. Recently, scholars examined whether frontier models could streamline the psychometric validation process by selecting criterion measures and formulating convergent validity hypotheses. However, adopting unverified computational workflows risks compromising clinical measurement integrity. A recent commentary highlights critical methodological flaws in initial validation experiments. Consequently, researchers urge the clinical community to establish strict evidentiary standards before implementing generative systems in psychological measurement.
Psychological assessment requires robust psychometric scales to measure psychiatric symptoms, cognitive traits, and emotional distress. Traditionally, human expert panels developed these instruments through painstaking literature reviews, qualitative interviews, and empirical pilot testing. However, traditional scale validation demands substantial clinical resources and time. In response, investigators tested whether frontier language models like GPT-4o and Gemini 2.0 Flash could accelerate psychometric workflows. Researchers specifically tasked these models with identifying criterion measures and generating hypotheses for convergent and discriminant validity.
Initial findings suggested that models could quickly generate plausible comparison instruments for novel measurement scales. For instance, the algorithms recommended standard anxiety inventories when evaluating scales designed for somatic distress. Consequently, some investigators viewed generative artificial intelligence as an efficient research assistant. Nevertheless, methodological experts urge significant caution. Semantic proximity across internet training data does not equal psychological construct validity. Therefore, mental health researchers must evaluate algorithmic suggestions using rigorous empirical standards rather than superficial plausibility.
A primary methodological flaw in current literature involves treating artificial intelligence as a single uniform entity. Scholars frequently make sweeping declarations regarding what AI can or cannot achieve in psychological science. However, this essentialisation obscures critical differences among distinct foundation models. For example, GPT-4o and Gemini 2.0 Flash possess disparate architectures, parameter counts, and alignment training. Thus, evaluating two specific commercial tools cannot support broad claims about generative artificial intelligence as a whole.
Furthermore, commercial providers continuously update their models behind the scenes without public notification. Consequently, a prompt tested during one month might yield completely different psychometric recommendations several months later. When scientists fail to document exact model checkpoints, scientific reproducibility suffers substantially. In addition, varying safety guardrails and reinforcement learning strategies heavily influence model outputs. Behavioral scientists must therefore identify specific model versions, parameter weights, and release dates in their methodologies. Ultimately, avoiding vague generalizations preserves the scientific rigor that clinical psychiatry requires.
Scientific replication forms the cornerstone of sound psychological research. Unfortunately, many exploratory investigations query language models through standard consumer web interfaces. While web chats appear accessible, consumer platforms introduce severe unmeasured confounding variables into scientific experiments. In particular, commercial web interfaces apply undisclosed system prompts, retain previous user histories, and modify system behavior dynamically based on server load. Consequently, two clinicians running identical prompts in web browsers often receive fundamentally inconsistent psychometric suggestions.
To ensure reproducibility, researchers must evaluate models exclusively through Application Programming Interfaces (APIs). Programmatic API access allows investigators to control and report key generation parameters, such as temperature, top-p, and random seed values. For instance, setting the sampling temperature to zero minimizes stochastic randomness across repeated trials. Furthermore, API pipelines automatically generate immutable, timestamped logs containing exact prompt inputs and machine outputs. This technical infrastructure permits independent scientists to inspect, reproduce, and verify experimental findings. Therefore, academic journals and research ethics boards should mandate API-driven protocols as an essential standard for computational validation studies.
Another critical vulnerability in early validation studies involves subjective outcome assessment. In preliminary trials, human evaluators frequently read model-generated hypotheses and subjectively judged whether the suggestions seemed appropriate. However, subjective human scoring introduces significant confirmation bias. Because frontier language models generate remarkably coherent and authoritative text, evaluators easily mistake rhetorical eloquence for scientific validity. Consequently, post-hoc qualitative appraisal cannot establish true psychometric accuracy.
Instead, researchers must formulate preregistered, objective benchmarks before conducting computational experiments. For example, investigators should test whether models can reconstruct empirically proven multi-trait multi-method matrices. In addition, automated algorithms must be scored against established psychometric gold standards using standardized mathematical formulas rather than subjective impressions. Specifically, rigorous validation requires demonstrating that models capture underlying theoretical constructs rather than superficial lexical similarities. Without objective benchmarks, researchers risk endorsing models that generate clinically dangerous fabrications. Therefore, establishing transparent evaluation criteria remains non-negotiable for advancing computational psychometrics.
Beyond technical hurdles, uncritical adoption of automated validation could severely damage psychological literature. For decades, behavioral science has battled construct proliferation and the jingle-jangle fallacies. These fallacies occur when researchers invent distinct labels for identical concepts or use identical labels for distinct conditions. Historically, the arduous process of scale development restricted unnecessary proliferation. However, automated systems can generate endless survey items within seconds. Consequently, unconstrained algorithmic generation threatens to overwhelm academic databases with redundant, poorly validated measurement tools.
Furthermore, automated models trained on Western literature perpetuate established conceptual errors. This limitation carries profound clinical risks for psychiatric practice in India. Indian clinicians frequently adapt psychometric scales across diverse linguistic and cultural environments. For instance, Indian patients frequently express depressive distress through somatic idioms rather than purely psychological descriptions. Because standard commercial models reflect Western diagnostic conventions, automated tools may recommend inappropriate criterion measures for Indian clinical populations. Therefore, mental health professionals in India must maintain strict human clinical oversight. By combining rigorous API standards with culturally grounded empirical field testing, clinicians can safely integrate emerging computational tools.
Consumer chat interfaces introduce uncontrolled variability that severely undermines scientific reproducibility. In particular, commercial web platforms frequently adjust underlying system instructions, modify model parameters, and retain conversational context across chat sessions. Consequently, different researchers cannot reliably reproduce identical experimental results using consumer browsers. Researchers must instead utilize programmatic APIs. APIs enable exact specification of temperature, random seed parameters, and system prompts, ensuring completely transparent and reproducible research outcomes across psychiatric and psychological studies.
Construct proliferation occurs when researchers create overlapping, redundant psychological concepts that describe the same underlying condition. Because generative models produce plausible scales and hypotheses within seconds, they drastically lower the barrier to introducing new measurement instruments. Furthermore, models learn from existing literature that already contains conceptual redundancies and jingle-jangle fallacies. Consequently, uncritical use of generative models threatens to inundate clinical psychiatry with poorly differentiated tools, compromising diagnostic consistency and evidence-based clinical decision-making.
Indian clinicians must approach automated scale adaptation with rigorous cultural scrutiny and empirical validation. Commercial language models primarily train on Western corpora and frequently overlook local idioms of distress, such as somatic symptom presentations common in South Asian populations. Therefore, clinicians must never rely solely on automated outputs for cross-cultural validation. Instead, practitioners should integrate robust API-driven tools with comprehensive human expert panels, standardized psychometric field trials, and localized normative data across diverse Indian linguistic groups.
Disclaimer: This content is for informational and educational purposes only and should not be considered as medical or professional advice. Always consult with a qualified healthcare provider for diagnosis and treatment of medical conditions. Refer to the latest local and national guidelines for clinical practice.
References
Read summarized clinical updates, watch expert medical content, and earn CME certifications right from your smartphone.
Open your smartphone camera to scan and install.


A methodological review of recommendations for incorporating large language models into psychological research, addressing scale validation, API standards, and construct proliferation in psychiatry.
Today

Patients with cardiovascular conditions face heightened health risks during extreme heatwaves. Discover findings from the ESC Patient Forum on climate change impacts, medication dilemmas, and actionable strategies for proactive heatwave preparedness in clinical practice.
Today
A large cohort study demonstrates that fetal growth restriction in a first pregnancy raises maternal cardiovascular risk within five years postpartum, including elevated rates of heart failure, stroke, and myocardial infarction. Clinicians must initiate proactive postpartum screening and cardiovascular prevention.
Today
An NHANES analysis reveals that meeting 24-hour movement guidelines significantly lowers the odds of cardiovascular disease, obesity, hypertension, and diabetes among adults with disabilities, emphasizing the power of combined physical activity, sleep, and limited sedentary time.
Today
A paired cadaveric study compared triple and quintuple percutaneous Achilles tendon lengthening. While quintuple hemisection showed numerically greater elongation, differences were not statistically significant.
Yesterday
A systematic review and meta-analysis of over 225,000 patients explores whether GLP-1 receptor agonists reduce the risk of glaucoma and ocular hypertension. While pooled data show a 31% lower risk, low certainty and wide prediction intervals urge cautious optimism and further randomized trial evaluation.
Today